01/the premise
People use AI. They don't believe it.
We're a small team making free AI tools built to earn that belief back. Two are live. This page is our case for why that matters to the people who build the models.
49%of American adults use an AI chatbot
59%lack confidence in the companies building it
Pew Research Center, Americans and AI 2026, June 2026.
02/public opinion
Adoption is outrunning trust.
United States, 2026. Pew Research Center, June 2026 · Stanford HAI AI Index 2026, public opinion.
Trust decides whether adoption lasts, and whether the labs' forecasts hold up. Low trust caps adoption, and adoption caps revenue. That makes public perception a line item for model providers, not a communications problem.
The public already has a word for what erodes it. Slop was the 2025 Word of the Year at Merriam-Webster, Macquarie and the American Dialect Society. Every invented number and every over-promised bot adds to it, and the bill lands on everyone building AI.
03/our build rules
What we build, and the rules it follows.
We build tools that give a person a good first experience of AI, on something that matters to them. We're llaizy about the right things and obsessive about the rules that keep slop out.
- 01
Free
No paywall in front of that first experience.
- 02
Frontier only
Claude and Grok on their makers' own routes, never through a reseller.
- 03
Guarded
Refuses rather than fabricates. Explains every change. Masks personal details in anything it stores.
What happens to every line.
A frontier model drafts, and before a person sees a word of it, seventeen checks compare the draft against the source. Any one of them can stop the run and say which rule broke. That refusal is the part we're proudest of: it keeps a person's name off something untrue.
aithe model wrote
Directed a team of 12, cutting close time by 40%.
refused"12" and "40%" are not in the source
what shipped
Ran the monthly close for a 6-person FP&A team.
sentevery fact traces to the source
One check out of seventeen, on one line.
The seventeen checks, in plain terms
- Employer namessurvive the rewrite untouched
check_employer_fidelity - Document shapekeeps the roles and sections you had
check_structure_fidelity - Clean textnothing truncated or malformed
check_text_integrity - Meaning helda rewritten line still means what yours meant
check_bullet_fidelity - Traceable linesevery line traces to something you wrote
check_bullet_provenance - Paddingcannot inflate beyond what the source supports
check_verbosity - Honest change listthe list of changes matches the changes made
check_change_summary - Numbers keptnumbers you earned do not get dropped
check_numeric_preservation - Invented numbersnumbers that were never yours do not get added
check_numeric_invention - Enough evidenceenough of your results carry through
check_numeric_coverage - No copying the adphrases from the posting stay out
check_job_text_non_copy - Unearned claimscredentials come from you, not the model
check_claim_provenance - Your identityname, phone, email and links never rewritten
check_contact_identity - Nothing missingrequired sections cannot go missing
check_section_completeness - Places agreelocations may not contradict the document
check_geo_coherence - Country rulesthe destination's rules are enforced
check_locale_rules - Model confidencethe model's own confidence has a floor
check_self_score
Named after the functions in the engine source, which is public. Check the checks.
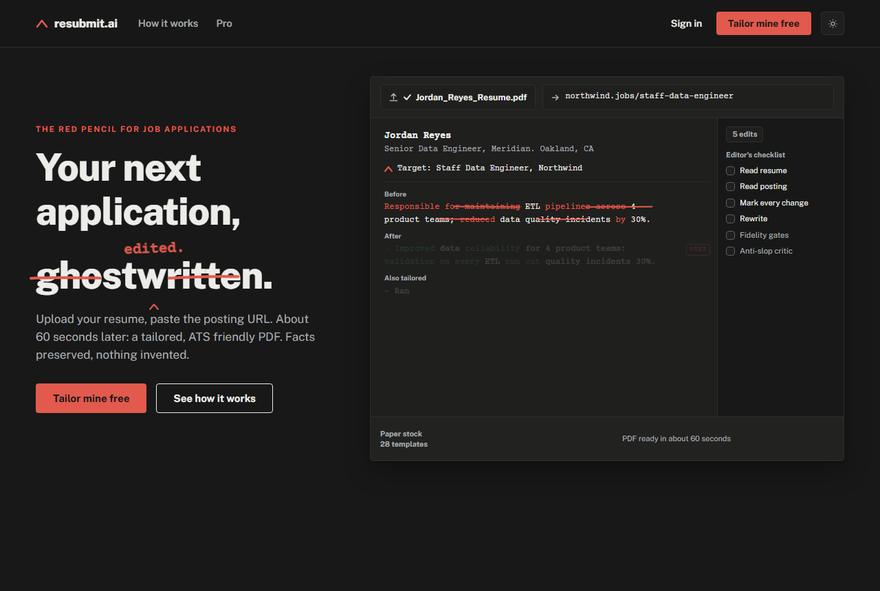
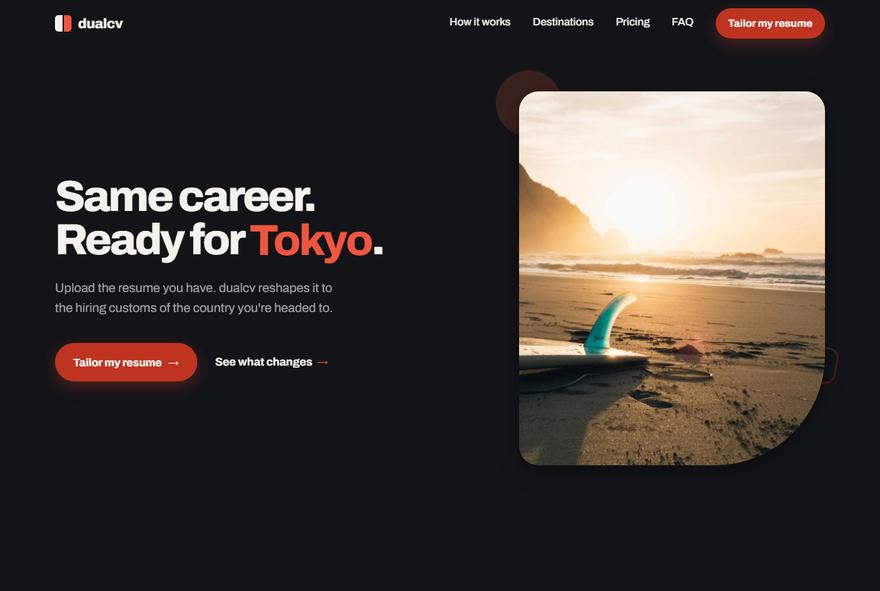
Two products. Both live, both free.
Same engine under both. Adding a country to dualcv touches no shared code, which is how a small team keeps two products honest without becoming two teams.
What credits buy.
Your model's reputation is built one document at a time. We build the documents, and we can show where the credits go.
01
Model credits
On Claude for the Pro path and Grok for the Quick path, first-party routes only.
02
Free documents
For real people, on the highest-stakes thing they write, with no paywall.
03
Good outcomes
Checked against the source, so nothing shipped can embarrass the model behind it.
04
Published numbers
Usage, refusal rates and outcomes, reported to you and to the public.
AnthropicClaude Sonnet 5, Pro path, first-party
xAIGrok 4.5, Quick path, first-party
MetaLlama 4, critic
AlibabaQwen3, fallback
OpenAIGPT-4o mini, last resort
We pin to the makers' own endpoints rather than a reseller's, because a quantized copy of a frontier model is not the model we evaluated. Names and marks belong to their owners and appear here because we run their models, not as a claim of partnership.
What we can show. What we can't yet.
We chose every model we run by blind evaluation, against a benchmark we keep for the purpose. The corpus, the checks and the reports are published, so a number we claim is a number you can reproduce.
2,879résumés in the benchmark
459real job postings
204expected-outcome pairs
17checks on every draft
Open questions we won't guess at
- The refusal rate at production scale. Our benches so far are small, and we will not put a number on this page until it is one we can defend.
- Whether a tool that refuses improves hiring outcomes for the person using it.
- Where deterministic checks beat a model judging a model, and where they don't.
- What a good first experience of AI does to a person's trust in the next one.
These are the questions a research partnership would be for. We can hand over the corpus and the checks.
Talk to a human.
human@llaizy.comModel creditsResearch partnersInvestment
All three reach the same inbox, read by the people who wrote the checks. Projected usage, the evaluation corpus and the reports are ready for any application form; ask and we'll send them. We answer within two working days.